Security Concerns Worth Evaluating in the Era of Generative Search
Today, a growing share of queries are answered directly by a large language model that reads the web on your behalf and hands you a synthesized paragraph, often with citations, sometimes with none.
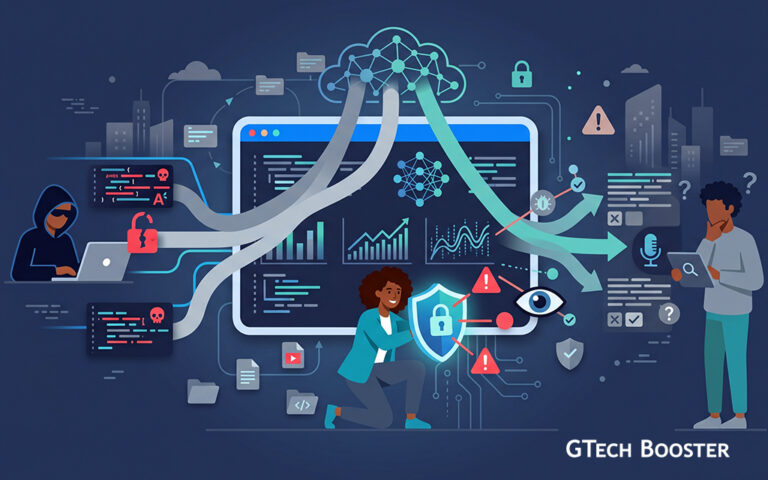
Search has changed shape. For two decades, “search” meant a ranked list of blue links that a human had to click, read, and judge. Today, a growing share of queries are answered directly by a large language model that reads the web on your behalf and hands you a synthesized paragraph, often with citations, sometimes with none. Google’s AI Overviews, ChatGPT search, Perplexity, and Microsoft Copilot have all normalized this pattern in the space of a couple of years.
That shift is convenient, but it also moves the trust boundary. When a human read the search results themselves, they were the last line of defense against an obviously spammy or scammy page. Now the model sits between the web and the user, and the model’s judgment, not the user’s, decides what gets repeated as fact. That single change opens up a set of security concerns that did not really exist in the old search paradigm, or existed in a much smaller form. Below is a tour of the ones worth taking seriously.
1. Answer-engine poisoning: the new SEO poisoning
Classic SEO poisoning is old news: attackers stuff a page with keywords or hijack a legitimate domain so their malicious link climbs the rankings, hoping a human clicks it. Generative search has produced a cousin of that attack, sometimes called AEO poisoning (answer-engine optimization poisoning) or GEO poisoning (generative-engine optimization poisoning).
The mechanism is different in an important way. Traditional SEO poisoning still needs the victim to click a link. Answer-engine poisoning skips that step entirely: the attacker crafts content specifically so that it gets pulled into the model’s retrieved context and then repeated in the model’s own synthesized answer, often without a visible link at all. As one security write-up put it, the lie arrives in the model’s own confident voice, stripped of the URL a user might otherwise have distrusted. That is a meaningful escalation, because it removes the one signal, a suspicious domain name, that a cautious human might have used to catch the scam.
This is already happening at scale, not just in research labs. Analysts have documented campaigns where attackers plant fake customer-support phone numbers inside Q&A-formatted content and upload it as PDFs to trusted .edu and .gov domains, precisely because those domains carry reputational weight with crawlers and with the ranking signals that feed LLM retrieval. The same technique has been observed seeded into YouTube descriptions, Yelp listings, and forum comments, essentially anywhere an answer engine is likely to crawl and trust text. When a user asks an AI assistant for an airline or cruise line’s support number, some of these campaigns have caused the assistant to confidently hand back a scam call center.
The unsettling part for defenders is that a model’s answer can look completely correct on the surface while its underlying retrieval pipeline is still pulling from compromised sources. Checking only the final output is not enough; the citations and retrieval trail matter too.
2. Indirect prompt injection through retrieved content
Answer-engine poisoning is really a specific case of a broader, and by most security researchers’ accounts still unsolved, problem: indirect prompt injection. Large language models process everything, system instructions, a user’s question, and any content pulled in from the web, as one continuous stream of tokens. There is no reliable architectural wall that tells the model “this part is a trusted instruction” and “this part is just data I retrieved.” At Infosecurity Europe 2026, an OWASP contributor described this plainly: prompt injection remains an unresolved architectural problem, precisely because there is no privilege boundary between system prompts, user queries, and retrieved content.
For a pure search-and-summarize product, the consequence is mostly reputational and informational: a poisoned page can steer the summary. But generative search is increasingly bundled with agentic capability, tools that can click links, fill out forms, or take actions on a user’s behalf. When that happens, indirect prompt injection stops being a misinformation problem and becomes an operational one. Instructions hidden in a web page, an email, or a shared document can cause an agent to exfiltrate data, send messages, or call tools it was never meant to invoke. Real-world cases along these lines have already surfaced. One documented incident involved a malicious prompt embedded in an email that made its way into a retrieval-augmented generation database through an AI email assistant, which then generated further emails carrying the same hidden instruction along with sensitive information, a pattern researchers likened to a self-propagating worm. Another involved instructions hidden in shared documents and calendar entries that, once retrieved through an enterprise search feature, triggered data exfiltration to external infrastructure.
3. Preference manipulation: gaming which sources get cited or recommended
A subtler variant of the poisoning problem targets not the factual content of an answer but the ranking judgment the model makes when it has to choose among competing sources, products, or plugins. Researchers call this preference manipulation, and it is the LLM-era equivalent of gaming Google’s PageRank.
In controlled studies, attackers who embedded subtle persuasive text into a product page were able to make an AI shopping assistant recommend that product roughly 2.5 times more often than it otherwise would have. In a separate experiment involving two competing plugins available to a model, a similar technique made the poisoned plugin two to eight times more likely to be selected. Extend that logic to news sources, medical advice, or financial products, and the concern becomes obvious: whoever understands how to write for the model’s retrieval and ranking behavior, rather than for the human reader, gains outsized influence over what billions of generative search queries will surface as the “best” or “recommended” option.
4. Hallucinated citations and false confidence
Even without an attacker in the loop, generative search introduces a plain reliability problem. Models sometimes attribute claims to sources that do not say what the model claims they say, or invent a citation altogether. Because these answers are delivered in fluent, authoritative prose, users tend to extend them more trust than they would a raw list of search snippets. Misinformation researchers flag this as a core vulnerability of retrieval-based systems: false content produced by the model can look indistinguishable from content faithfully drawn from a legitimate source, and the average user has no easy way to tell the difference without independently checking every citation.
5. Agentic search and the expanded blast radius
The most consequential change underway is the move from generative search that only answers questions to generative search that also acts: browsing agents that click through pages, fill out forms, complete purchases, or manage accounts on a user’s behalf. This is a genuine capability upgrade, but it multiplies the stakes of every vulnerability above.
Security researchers now describe the core enterprise AI risk picture as spanning four areas: prompt injection itself, agents and tool use (where a manipulated output can trigger a real-world action instead of just a bad sentence), the retrieval and data layer (where proprietary or sensitive data can leak or be poisoned), and “shadow AI,” unsanctioned AI tools operating outside an organization’s visibility or controls. When an AI system is only generating text, a successful attack produces a bad paragraph. When that same system can also invoke tools, the identical attack can produce an unauthorized purchase, a leaked credential, or an exfiltrated document. Security frameworks like NIST’s Generative AI Profile now explicitly classify prompt injection and data poisoning as information-security risks, and supply-chain integrity, meaning the safety of every plugin, connector, and data source an agent touches, as its own risk category.
6. Enterprise data exposure through connected search
Many organizations are wiring generative search into internal knowledge: email, shared drives, ticketing systems, calendars. This is where retrieval-augmented generation (RAG) delivers real productivity value, and where it also inherits every access-control problem an organization already had, plus new ones layered on top. If an AI search feature has broader read access than the employee using it, or if the underlying retrieval index does not respect the same permission boundaries as the source systems, a single query can surface information the user was never supposed to see. Vendors have already had to restructure products in response: one major enterprise search feature was separated from its associated AI assistant specifically after researchers demonstrated that instructions hidden in ordinary documents could be retrieved and used to trigger unauthorized data exfiltration.
7. Brand and narrative manipulation at the training layer
A longer-horizon concern is less about a single malicious query and more about slow, cumulative influence. If enough poisoned or biased content about a brand, a product category, or a contested topic gets indexed and repeatedly cited, it can shape how models describe that subject well after any individual poisoned page is taken down, especially once that content has influenced a training or fine-tuning cycle rather than just a live retrieval index. Marketers and security teams alike are only beginning to build monitoring practices for this, comparable to brand-reputation monitoring but aimed at what AI systems say rather than what search engines rank.
What meaningfully reduces the risk
None of this argues against using generative search, it argues for treating it the way security teams learned to treat any other new attack surface: with monitoring, skepticism, and layered defenses rather than blind trust. A few practical points that come up consistently in current guidance:
- Treat retrieved content as untrusted input, not as instructions. Products that let a model act on what it reads from the open web need a real boundary between “information to consider” and “commands to follow.” This is a design problem, not something a user can patch on their own.
- Prefer answers with visible, checkable citations, and actually check them for anything consequential: medical, financial, legal, or security-relevant claims. A confident tone is not evidence.
- Scope agentic permissions tightly. An AI agent that can browse should not, by default, also be able to purchase, message, or move money without a separate confirmation step.
- Apply the same access controls to AI-connected retrieval that you’d apply to the underlying systems. If an employee couldn’t see a document through the file share, an AI search layer built on top of that file share should not be able to surface it either.
- Watch for anomalies, not just outages. A sudden shift in how an AI system describes your brand, product, or organization can be a signal of poisoning, the same way a sudden traffic anomaly can be a signal of a breach.
Generative search is a genuine leap in convenience, but it collapses a step, human judgment before the click, that used to catch a lot of low-effort scams and misinformation for free. Understanding where that step disappeared is the first move toward putting some version of it back.
More Information ℹ

Conversation
Login to comment.
Log In / Register