When to Go Microservices and When to Go Monolithic
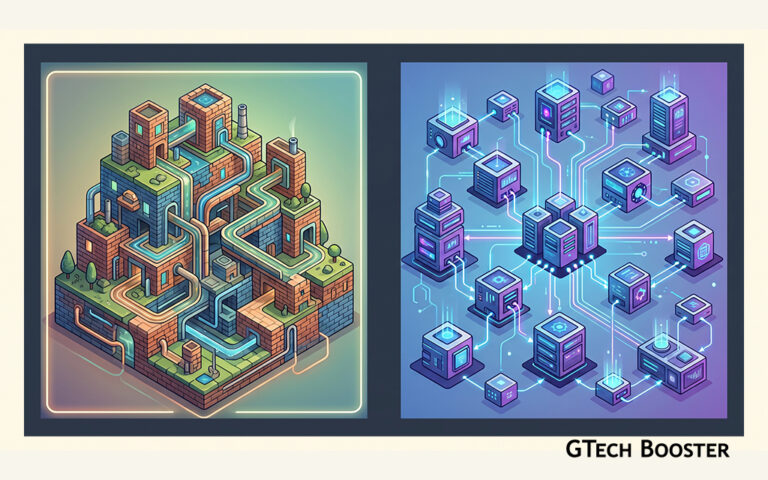
Few debates in software engineering generate as much noise as the microservices versus monolith question. For most of the 2010s, microservices were treated as the default answer for any serious application, largely because companies like Netflix, Amazon, and Uber talked publicly about their success with them. What often got lost in that conversation is that these companies adopted microservices after they hit specific organizational and scaling problems, not before. This article breaks down what each architecture actually is, the real tradeoffs involved, and how to decide which one fits your situation.
What a Monolith Actually Is
A monolithic architecture is a single, unified codebase and deployable unit. All the application’s functionality, the user interface logic, business rules, data access, and background jobs, lives in one process and typically talks to one database. When you deploy a monolith, you deploy the whole thing at once.
Monoliths get a bad reputation because the word conjures images of tangled, unmaintainable “big balls of mud.” But a monolith does not have to be a mess. A well-organized monolith uses clear internal module boundaries, separates concerns cleanly, and can be just as maintainable as a set of services, sometimes more so, because there is only one codebase to reason about.
What Microservices Actually Are
A microservices architecture breaks an application into a collection of small, independently deployable services, each responsible for a specific business capability. These services communicate over a network, usually through HTTP APIs, message queues, or event streams, rather than through direct in-process function calls. Each service typically owns its own data store, so there is no single shared database that every part of the system reaches into.
The appeal is real: teams can deploy independently, scale specific services based on their own load, and use different technologies where it makes sense. The cost is also real: you have traded a hard problem inside one process for a hard problem across a network, and network problems are harder.
The Core Tradeoff
Every decision here comes down to one tradeoff: microservices trade simplicity for flexibility and independence, while monoliths trade some flexibility for simplicity and speed.
With a monolith, calling a function is fast, reliable, and easy to debug because everything runs in one process. There is no network latency, no partial failure to handle, and no need to worry about API versioning between internal components. The downside is that everything is coupled by default. A change in one part of the code can accidentally affect another, the whole application has to be redeployed for any change, and as the codebase and team grow, coordination becomes harder.
With microservices, each service can be built, deployed, and scaled independently, which is valuable when different parts of a system have very different load patterns or when multiple teams need to move without stepping on each other. The downside is that you now have distributed system problems: network calls can fail or time out, data consistency across services becomes genuinely difficult, tracing a single user request across a dozen services requires real tooling, and testing the system as a whole is far more complex than testing a single codebase.
Signals That Point Toward a Monolith
You are early stage or the product is still finding its shape.
When requirements change weekly and the boundaries of your domain are not yet clear, splitting into services means you are guessing at boundaries that will likely be wrong. Refactoring code inside one codebase is cheap. Refactoring the boundary between two live services, with data migrations and API contract changes, is expensive.
Your team is small.
Microservices introduce real operational overhead: multiple deployment pipelines, service discovery, distributed logging, monitoring across services, and often multiple on-call rotations. A team of five to ten engineers usually cannot support that overhead well and gets more value from spending that time on the product itself.
You do not yet have a scaling problem that a monolith cannot solve.
Modern monoliths can scale a long way through horizontal scaling of the whole application, caching, database read replicas, and vertical scaling. Many companies serving millions of users still run successful monoliths. Do not adopt the operational complexity of microservices to solve a scaling problem you do not actually have yet.
Strong consistency matters a lot in your domain.
If your application deals with financial transactions, inventory counts, or anything where you need atomic, all-or-nothing updates across what would be different services, a single database and a single transaction boundary makes this dramatically simpler. Distributed transactions across services are possible but add significant complexity through patterns like sagas and eventual consistency.
You want to ship fast and iterate.
Deploying a monolith is a single, well understood pipeline. There is less coordination overhead when a feature touches multiple parts of the system, since it is all one deploy.
Signals That Point Toward Microservices
Different parts of your system have very different scaling needs.
If one part of your application handles heavy, bursty traffic, such as image processing or video encoding, while the rest of the application has steady, moderate load, splitting that piece out lets you scale it independently instead of scaling your entire application to handle the load of its busiest component.
Multiple teams need to work independently without blocking each other.
Once an engineering organization grows past a certain size, usually somewhere in the range of dozens of engineers working on the same product, a shared monolith codebase becomes a coordination bottleneck. Merge conflicts, shared deployment windows, and the blast radius of one team’s bug affecting everyone else’s release become real costs. Microservices let teams own a service end to end, deploy on their own schedule, and limit the blast radius of failures.
You have genuinely different technical requirements across parts of the system.
If one part of your system is best served by a language or runtime that does not fit the rest of your stack, for example a machine learning inference service that benefits from Python’s ecosystem while your core application is in Java or Go, services let you make that choice locally instead of forcing the whole system onto one stack.
You need independent fault isolation.
In a monolith, a memory leak or crash in one module can take down the entire application. In a services architecture, a failure in a non-critical service, such as a recommendation engine, does not have to take down checkout or login, provided you design for graceful degradation.
Your organization has already built the operational maturity to support it.
This is the signal people skip most often. Microservices require investment in things like centralized logging, distributed tracing, service meshes or API gateways, automated deployment pipelines per service, and a mature approach to monitoring and alerting. If that infrastructure does not exist yet, moving to microservices before building it tends to produce a distributed system that is harder to operate than the monolith it replaced.
The Middle Ground: The Modular Monolith
A pattern that has gained real traction as a corrective to premature microservices adoption is the modular monolith. This is a single deployable application, like a traditional monolith, but internally organized into clearly separated modules with well defined boundaries and minimal coupling between them, closer to how a microservices system would be organized logically, just without the network calls between the pieces.
The advantage of this approach is that it gives you much of the organizational clarity of microservices, clear ownership boundaries, limited coupling, the ability to reason about one module at a time, without the operational cost of a distributed system. If a module eventually needs to become its own service because of a genuine scaling or team ownership need, the clean internal boundaries make that extraction far easier than trying to carve services out of a genuinely tangled codebase.
Many teams that eventually move to microservices successfully describe following roughly this path: start as a monolith, keep the internals modular and disciplined, and extract services only when a specific, concrete pain point demands it, not preemptively.
A Practical Decision Framework
When deciding, it helps to ask a short set of concrete questions rather than defaulting to whichever architecture is currently fashionable.
- Do you have a scaling problem today that a monolith with horizontal scaling and caching cannot solve. If not, you likely do not need microservices yet.
- Do multiple teams need to deploy independently without blocking each other, and is that actually happening today, not hypothetically in the future.
- Do different parts of your system have meaningfully different load profiles or technical requirements.
- Does your organization already have the operational tooling, logging, monitoring, deployment automation, to support a distributed system, or are you willing to build that first.
- Is your domain still changing quickly, in a way that would make service boundaries premature and expensive to redraw.
If most of your honest answers point toward “not yet” or “we do not know,” a monolith, ideally a modular one, is almost always the better starting point. If you have concrete, current pain around team coordination, scaling specific components, or fault isolation, and you have the operational maturity to support a distributed system, microservices become a reasonable and often necessary next step.
Wrapping Up
There is no universally correct architecture, only the right architecture for a given team, product stage, and set of operational constraints. Microservices solve real problems around independent scaling, team autonomy, and fault isolation, but they solve those problems by introducing genuine distributed systems complexity that has to be paid for somewhere, usually in engineering time and operational maturity. Monoliths solve for simplicity and speed of iteration, at the cost of coupling and, eventually, coordination overhead as a codebase and team grow large enough.
The companies most often cited as microservices success stories did not start that way. They grew into the need, hit specific and painful limits with a monolith, and then made a deliberate, well resourced move. That order matters. Choosing microservices because of what a scaling company needed years into its life, rather than because of what your product and team need today, is one of the most common and costly architecture mistakes in modern software engineering.
More Information ℹ
Conversation
Login to comment.
Log In / Register